TL;DR
Key takeaways
- A schema compare tool compares database schemas across environments, detects drift and generates deployment-ready SQL, automating the last manual step left in a CI/CD pipeline
- Gartner expects more than 70% of organisations to formalise database change automation by 2026, up from less than 30% in 2022, as data complexity, regulation and engineering velocity all rise
- 4DAlert tags every object NEW, MODIFIED, SYNCED or DELETED and turns the selected objects into a dependency-ordered SyncUp Script in seconds
- DROP statements are commented out by default so nothing destructive executes until someone activates them, and the script can be pushed straight to GitHub Actions or Azure DevOps
- Screen tools for real object-type coverage, declarative script generation, default-on DROP protection, multi-database support, direct DevOps push and a full audit trail
Mid-size companies lose an average of $100,000 an hour due to unplanned database outages.
One of the most frequent reasons for CI/CD pipeline failures is database changes. Application code is automatically versioned, reviewed, tested and deployed. The database, more often than not, still relies on some individual to write the ALTER scripts, sequence them properly and push them to production without error. That person is typically the most senior engineer, and he’s spending his Friday afternoon on work that should’ve been automated years ago.
It’s not just about inefficiency. It’s a risk. Each manual change from developer to production is a potential point of failure — missing a dependency, running a DROP that shouldn’t have been, silently truncating data because of a column type change. The teams who have had a production failure due to a poor migration script don’t forget it. And a lot of them are still doing it the same way next quarter.
The industry has addressed this issue for application code. Continuous Integration, automated testing and deployment pipelines are the norm. However, the database has been a dark corner for a long time, partly because schema changes are more risky and partly because the tooling to automate the changes safely has been less mature or complete.
That’s changing. This blog explains what schema compare tools are, how they can be used in a modern CI/CD pipeline, and how to differentiate the good from the bad. We illustrate how 4DAlert does this in practice along the way.
Why Database Changes Break Pipelines
If multiple developers are developing the same database at the same time, where each developer is making changes to tables, views, stored procedures or functions, merging those changes is not as easy as it sounds. The questions that arise in each release are:
- Which changes happened in DEV that haven’t reached QA or PROD yet?
- Are there conflicting modifications to the same object across branches?
- What is the correct sequence to run scripts without breaking dependencies?
- Did anyone change a column type in a way that causes data truncation?
- Is there a DROP statement hiding somewhere that nobody explicitly approved?
If you don’t have tooling, the answers to these questions will be found by comparing environments, reading through SQL files and on the basis of who has the most institutional knowledge. That process isn’t scalable, and that’s the gap schema compare tools are designed to fill.
Start with a Saved Configuration, Not a Blank Form
4DAlert begins with Comparison Configurations — source, target, object types, and preferences saved once and reused every time. Teams running recurring comparisons don’t re-enter connection details on every run; they open a saved configuration and compare.
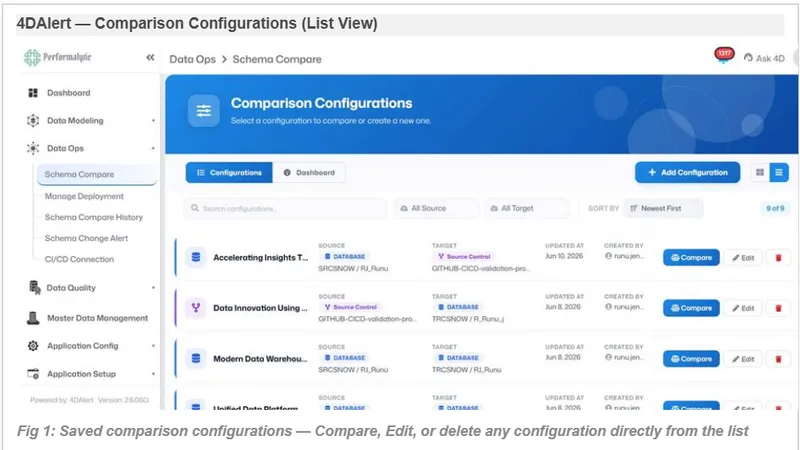
Fig 1: Saved comparison configurations — Compare, Edit, or delete any configuration directly from the list
For each configuration saved, the source, target, last updated date and the name of the user who created the configuration are displayed. Compare is executed with the same settings as before with only one click. No need to re-enter object type selections, schemas, or system names.
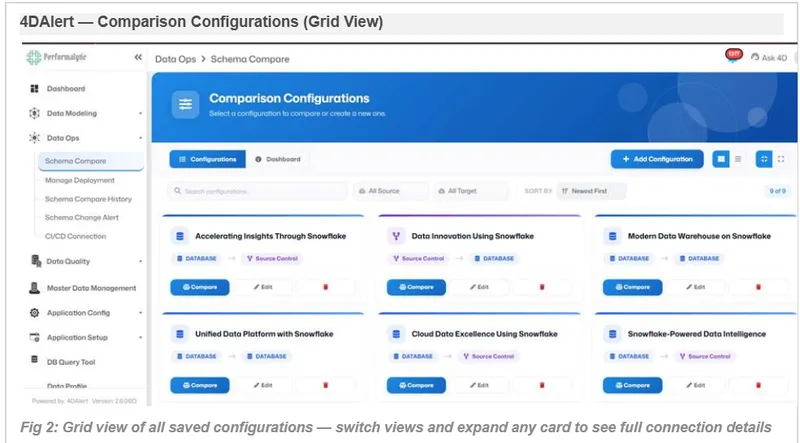
Fig 2: Grid view of all saved configurations — switch views and expand any card to see full connection details
Whether it’s database-to-database, database-to-source-control, or source-control-to-database, configurations can be made for all common directions a team needs to compare, including validating a release branch against production or syncing two live environments.
Setting Up a Comparison — Source, Target, and Scope
There are a few fields to create or edit a configuration in 4DAlert: a configuration name, a source and a target. Both sides can be a live Database connection or a Source Control branch, providing complete flexibility in comparison team structure.
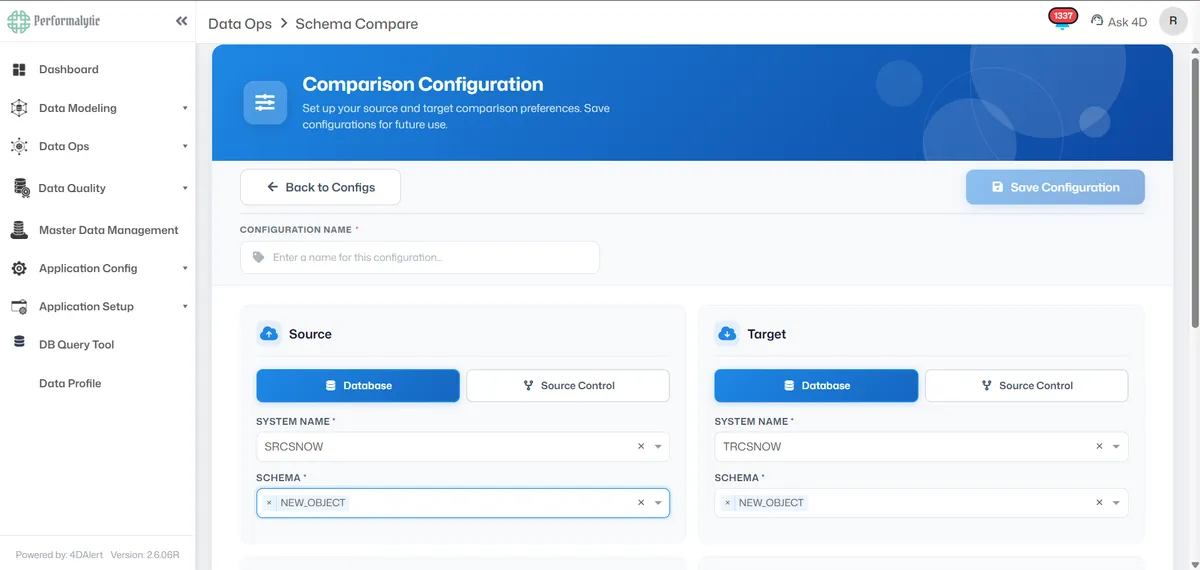
Fig 3: Configuration setup — name the configuration, then choose Database or Source Control for both Source and Target
Below the source and target fields, the same configuration screen lets you scope exactly what gets compared and how destructive changes are handled:
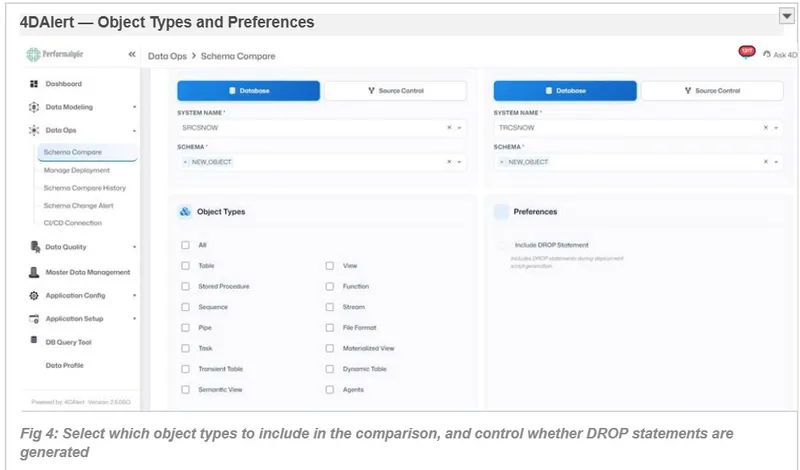
Fig 4: Select which object types to include in the comparison, and control whether DROP statements are generated
The full list of supported object types includes Tables, Views, Stored Procedures, Functions, Sequences, Streams, Pipes, File Formats, Tasks, Materialized Views, Transient Tables, Dynamic Tables, Semantic Views, and Agents — giving teams complete control over what is and isn’t in scope for each comparison run.
Three Ways to Compare — Database or Source Control, Either Side
With Source and Target both having the option to be set to Database or Source Control, teams have three different comparison scenarios from the same configuration screen, covering all directions a release workflow actually needs:
Database → Database
Compare two live environments directly, e.g. DEV vs PROD, to identify drift between live systems.
Database → Source Control
Compare a live database to a Git branch to make sure that the database is the same as the one in source control, or to create a script that updates source control with a live environment.
Source Control → Database
Compare a Git branch or repository with a live database — the most common pre-deployment step, to ensure that a release branch is ready for pushing to a target environment.
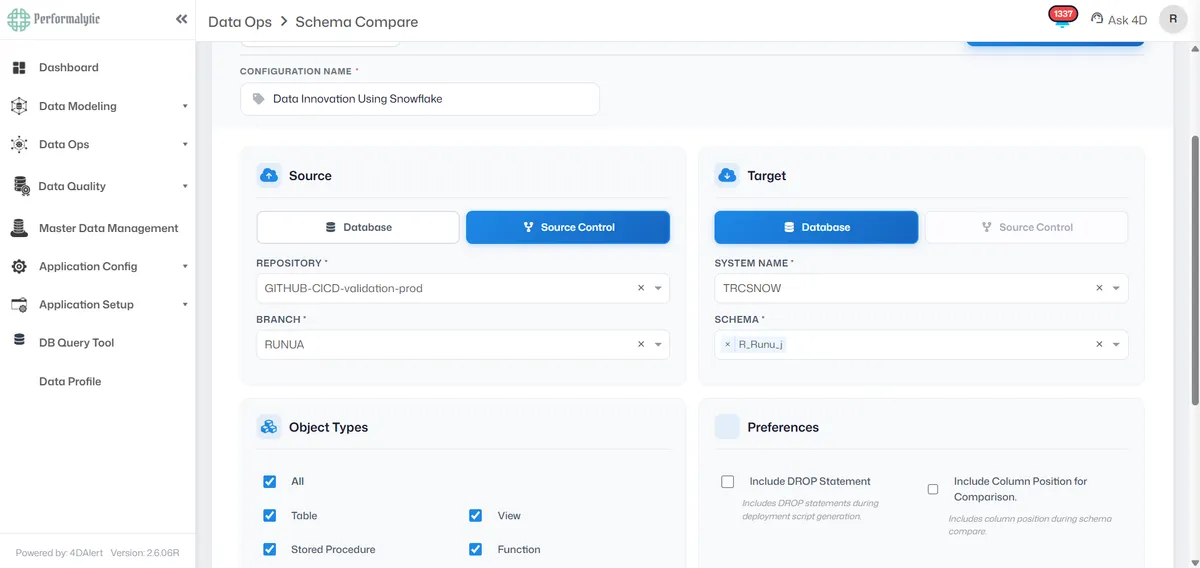
Fig 7: Source set to Database (SRCSNOW), Target set to Source Control — comparing a live database against a GitHub repository and branch
In both cases, the Repository and Branch fields replace System Name and Schema for whichever side is set to Source Control. Object type selection and preferences work identically regardless of which combination is chosen — the comparison engine treats a Git branch and a live database as equivalent sources of truth.
Include DROP Statement — Controlling How Destructive Changes Appear
Another preference that directly affects the deployment script generated is Include DROP Statement, which sits alongside Include Column Position. This setting will affect whether the dropping of a table, column, or other object that exists in the target but not the source is included in the SyncUp Script as live, executable SQL or is commented out as a visible warning.
| Unchecked (default) | Checked |
| DROP statements are still generated, but written as SQL comments in the deployment script. The script displays exactly what will be dropped, but nothing destructive will execute until someone uncomments it manually first. | DROP statements are live and executable SQL — no comments. The deployment script will actually drop the flagged objects when it is run and no manual step is needed to “activate” the flagged objects. |
Why this matters: This is the safer default for most teams — it provides complete visibility of what would be removed without any risk of an accidental DROP running in production. Checking it is suitable for fully automated pipelines where the team has already reviewed and approved destructive changes upstream, and they wish for the deployment script to run smoothly without a manual edit step. Regardless, the SyncUp Script always displays all the DROPs — the setting only determines whether or not it will execute automatically or be left for a human to do.
Include Column Position — A Preference Worth Understanding
Among the comparison preferences sits a setting that’s easy to overlook but changes results significantly: Include Column Position for Comparison. This preference applies specifically to Tables, Transient Tables, and Dynamic Tables in Snowflake, and it controls whether column order counts as a difference.
| Unchecked (default) | Checked |
| Column order is ignored. If both source and target have the same columns with the same names and types — regardless of the order they appear in — the object is reported as SYNCED. | Column order is treated as part of the schema. If the same columns appear in a different sequence between source and target, the object is reported as MODIFIED, even though the column count and definitions are identical. |
Why this matters: Two tables can have identical columns but be flagged as MODIFIED purely because of ordering — for example if one environment added a column in the middle of a table rather than at the end. Teams that care about exact column-by-column layout (some BI tools and downstream integrations are position-sensitive) should enable this preference. Teams who only care about the actual column set should leave it unchecked to avoid noisy false positives in the comparison results.
Comparison Output — Four Clear Statuses
Running a saved configuration produces an object-by-object breakdown. Every object in 4DAlert’s Schema Compare is tagged with one of four statuses:
NEW
Exists only in source. Will be created in target.
MODIFIED
Exists in both but differs. Script will align them.
SYNCED
Identical in both environments. No action needed.
DELETED
Exists only in target. Will be dropped on deploy.
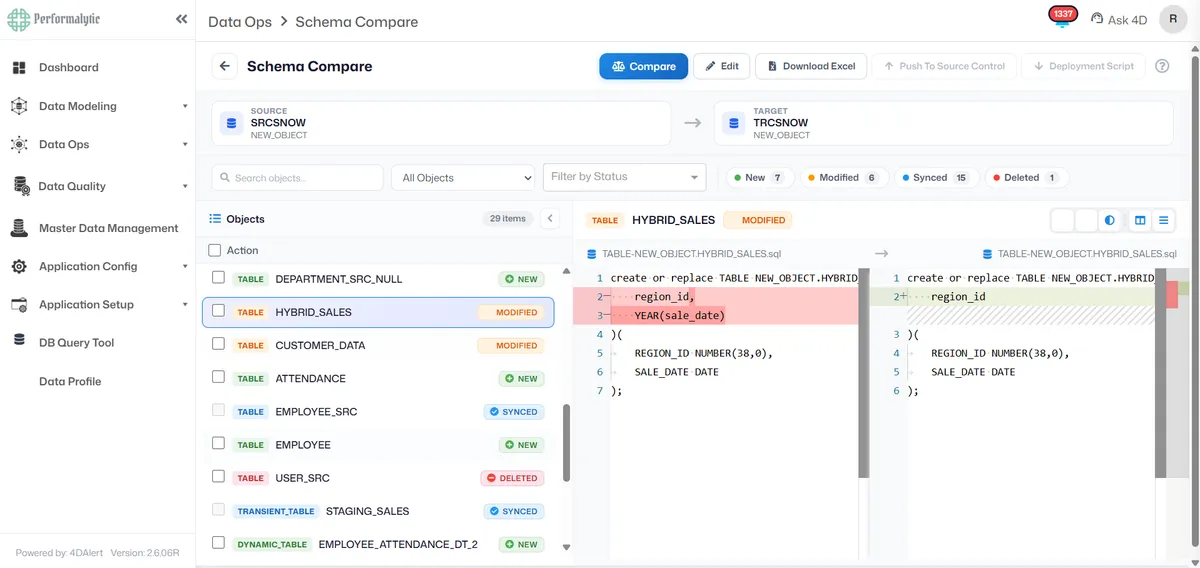
Fig 5: Comparison output — filter by status (New, Modified, Synced, Deleted), then inspect any object’s full DDL diff side-by-side
Selecting any object opens a full side-by-side DDL comparison, with additions and removals highlighted line-by-line — exactly what changed, with no ambiguity about what the deployment script will do.
From Diff to Deployment Script — Automatically
Knowing what is different is only useful if you can act on it. The best result of any schema compare workflow is a deployment-ready SQL script — one that can be reviewed, approved and executed without anyone having to write a single line of SQL by hand.
| Without automation | With 4DAlert |
| Hand-written ALTER scripts, manual sequencing, and a hope that the dependency order is right. You find out if it worked in production. | Select objects, generate the SyncUp Script automatically — right order, right syntax, every time. |
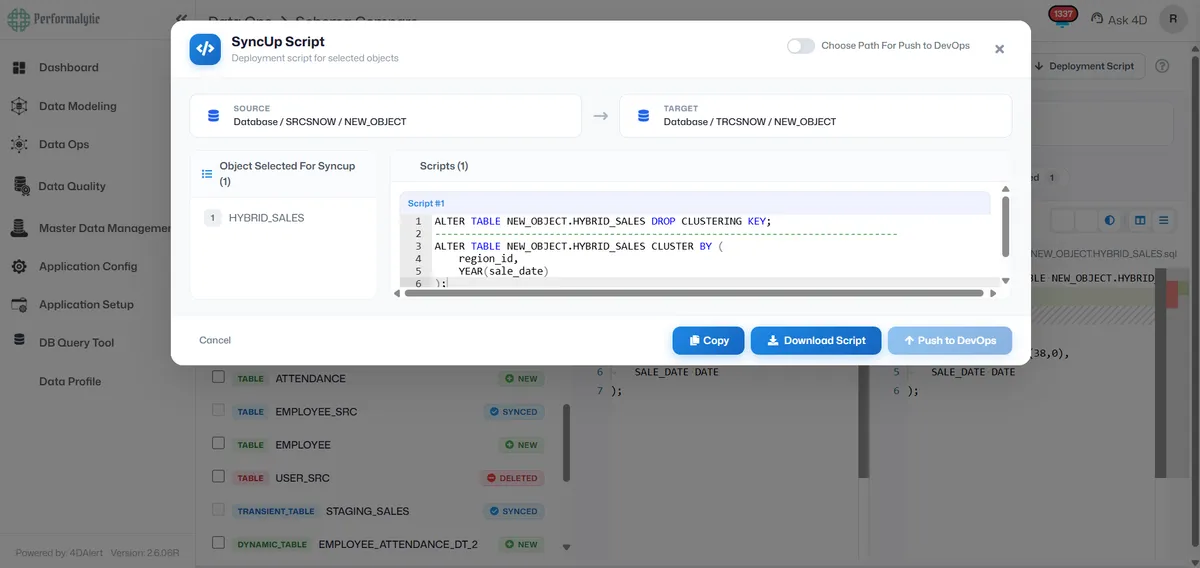
Fig 6: Auto-generated SyncUp Script for the selected object — Copy, Download, or Push directly to DevOps
The SyncUp Script can be copied directly, downloaded as a file for manual execution, or pushed straight to source control — Git, Azure DevOps, or any connected CI/CD pipeline — with a single click. There’s no separate export step and no manual file handling between comparison and deployment.
The SyncUp Script is not just a list of SQL statements. It is a sequenced, dependency-aware deployment plan — generated in seconds, not hours.
Supported Databases — Built for Every Modern Data Stack
4DAlert is built as a multi-database platform from the ground up. Most enterprise environments don’t run a single database — they run several, often across cloud and on-premise, relational and non-relational. 4DAlert consolidates schema management for all of them under one comparison and CI/CD workflow:
Snowflake
Cloud Data Platform. Full object coverage — tables, views, procs, streams, pipes, tasks, dynamic tables, sequences. Deep native CI/CD integration.
SQL Server
On-premise · Azure SQL. Tables, views, stored procedures, functions, triggers, indexes, and schema-level objects across on-premise and Azure SQL.
Oracle
11g — 21c · Oracle Cloud. Packages, package bodies, sequences, synonyms, and complex dependency ordering across Oracle 11g through 21c.
PostgreSQL
Self-hosted · RDS · Aurora. Functions, triggers, schemas, extensions — across self-hosted, RDS, Aurora, Supabase, and Neon environments.
MySQL / MariaDB
Self-hosted · RDS · Cloud SQL. Tables, views, stored routines, triggers, and indexes across MySQL and MariaDB deployments, on-premise or managed.
Azure Synapse
Dedicated · Serverless pools. Schema compare across dedicated SQL pools and serverless environments with full Azure DevOps integration.
Amazon Redshift
AWS · Spectrum. Schemas, tables, views, and stored procedures compared and deployed with the same pipeline as other environments.
Google BigQuery
Datasets · Cloud SQL. Dataset and table schema comparison across BigQuery projects, with native support for partitioned and clustered tables.
MongoDB
Atlas · Self-hosted. Collection and document schema comparison for MongoDB Atlas and self-hosted clusters — bringing schema discipline to NoSQL.
Databricks
Delta Lake · Unity Catalog. Schema compare across Delta Lake tables and Unity Catalog objects for modern lakehouse architectures.
IBM Db2
On-premise · Cloud. Tables, views, stored procedures, and schema objects across Db2 for enterprise on-premise and cloud deployments.
SAP HANA
On-premise · Cloud. Schema and calculation view comparison for SAP HANA environments — built for enterprise data landscapes.
Multi-environment, multi-database — all in one pipeline. The same comparison logic, script generation, and CI/CD integration — across all twelve supported platforms. A team running Snowflake for analytics, SQL Server for their app backend, MongoDB for a microservice, and Databricks for their lakehouse can manage schema changes across all of them from a single tool.
Real Business Impact
Automating schema management is not just a developer quality-of-life improvement. It has direct, measurable consequences for the business — in time saved, risk reduced, and revenue protected.
80%
Reduction in effort spent on schema change management.
95%
Fewer deployment failures caused by manual script errors.
~0
Manual interventions needed once the pipeline is set up.
One enterprise customer — a manufacturer with over 5,000 database objects across multiple Snowflake environments and development teams in different time zones — reached these numbers after implementing 4DAlert’s schema compare pipeline. The team didn’t change. The stack didn’t change. Only the process did.
The business consequences of not automating are equally concrete:
Engineering Cost
Senior engineers spending 4–8 hours per release cycle on manual migration scripts — time that compounds across every sprint, every quarter, every year.
Deployment Risk
One incorrect dependency or incorrect ALTER sequence can cause production to fail. Mid-size companies lose an average of $100,000 an hour due to unplanned database outages.
Compliance Exposure
In the absence of an automated audit trail, teams will not be able to show auditors what has changed in production databases. The consequences of SOX and GDPR violations are severe and costly.
Talent Retention
Engineers leave for teams where deployment is automated, not teams where it’s a ritual of stress. Manual release processes measurably contribute to engineering attrition.
Common Schema Compare Use Cases
4DAlert’s Schema Compare is used across a wide range of scenarios — from routine pre-release environment syncing to compliance-driven audit requirements. Here are the six most common:
Pre-release Environment Sync
DEV, QA and STAGING environments should be in sync before each release. 4DAlert automatically runs the comparison for each environment pair and creates a sequenced sync script, without manual diffing.
Hotfix Propagation
A critical bug fix is applied directly to PROD. 4DAlert will detect the drift, generate the reverse-propagation script and ensure that DEV and staging are in sync before the next merge window.
New Developer Onboarding
A new engineer sets up a local database. Instead of running through setup docs and hoping nothing is out of date, 4DAlert compares their local schema against DEV and generates the exact scripts needed to align.
Multi-team Schema Governance
Several teams are using the same database instance. 4DAlert serves as the governance layer, monitoring all schema changes across teams, identifying conflicts, and generating a single deployment script.
Compliance & Audit Readiness
SOX, GDPR and internal audit regulations require a complete audit trail of changes to production databases, when and who. This is automatically tracked by 4DAlert’s audit trail, without manual logging.
Disaster Recovery Validation
For a DR failover, the recovery environment should be exactly the same as production. 4DAlert validates the schema parity between the primary and DR environments and creates remediation scripts for any schema drift identified.
Where This Fits in Your CI/CD Pipeline
4DAlert integrates directly with GitHub Actions and Azure DevOps. Schema compare runs automatically as part of your existing pipeline — triggered by a commit or pull request, with no manual login required:
- Developer commits schema change to source control
- Pipeline triggers — 4DAlert schema compare runs automatically
- Diff generated: NEW, MODIFIED, and DELETED objects identified across all DB types
- Deployment script auto-generated, dependency-ordered per database engine
- DROP operations and data-risk changes flagged for human approval
- On approval, script pushed to DevOps and deployed to target environment
- Full notifications sent with diff summary — devs, DBAs, and stakeholders
The result is a database deployment workflow that looks and behaves exactly like your application deployment workflow — automated, traceable, and reviewable before anything reaches production.
How to Choose a Schema Compare Tool
- Covers the actual object types. Tables and columns are self-explanatory. There are views, procedures, sequences, streams, tasks, dynamic tables and more in real environments.
- Declarative script generation. The desired end state is defined. The tool identifies the correct path (CREATE vs ALTER), dependency order, risk flagging.
- The DROP protection is enabled by default. Destructive operations must be explicitly approved, commented out and flagged. Never silent.
- Multi-database support. If you are using more than one database engine with your stack, your schema compare tool should include all of them.
- Immediate push to DevOps. Generated scripts are directly uploaded to GitHub Actions or Azure DevOps — not a download folder that is manually uploaded.
- Full audit trail. All changes recorded — what ran, who activated it, pass/fail. Essential for SOX and GDPR.
Audit trail is the compliance requirement most tools are missing. All schema changes performed by 4DAlert are recorded, including what changed, what script was used, who initiated the change, and the success or failure of the change. This is not an option for teams that are subject to SOX, GDPR or their own data governance requirements. It is what manual deployment processes can’t structurally provide.
Conclusion
Industry trends: this problem is only going to get worse. The need to automate database schema management is growing at an increasing pace, bolstered by three forces that are coming together: increasing data complexity, more stringent regulatory demands, and greater demand for engineering velocity.
Database DevOps Adoption
By 2026, more than 70% of organisations will have formalised database change automation as a component of their DevOps practice, up from less than 30% in 2022, says Gartner.
Multi-cloud Data Platforms
Today, most enterprise data teams have two or more cloud database platforms running at the same time. Schema management tooling that is limited to a single platform is becoming less and less effective.
A Strong Focus on Regulation of Data
Verifiable audit trails are essential for data structure changes across all regulatory frameworks, including SOX, GDPR, DORA, and new AI governance laws. This is not possible at scale with manual processes.
Move Data Teams to the Left
The same shift-left philosophy that brought testing earlier into the application pipeline is now bringing schema validation earlier — before it gets to production.
Why This Problem Matters — Now
Most engineering teams have a database as the final manual process in an otherwise automated delivery pipeline. It is the place where the most time is spent by experienced engineers, where the most incidents in production occur, and where it is most difficult to meet compliance requirements. It’s not a nice-to-have to solve it. It’s the last of the full DevOps practice.
The benefits of automating schema management are compounded: quicker release cycles, reduced incidents, reduced compliance effort, and engineers who can work on product instead of migration scripts. The teams that aren’t taking a cost — one that is hidden, but one that is ongoing — in terms of time, in terms of risk, and in terms of engineering talent that eventually goes elsewhere where it isn’t as frustrating.
Frequently Asked Questions
What is a schema compare tool?
A schema compare tool compares database schemas across environments, identifies differences, and generates deployment-ready SQL scripts to keep databases synchronized while reducing manual effort.
Why are schema compare tools important for Database CI/CD?
Schema compare tools automate database change management, detect schema drift, generate accurate deployment scripts, and help prevent errors that can cause CI/CD pipeline failures.
How does 4DAlert automate database schema comparisons?
4DAlert compares live databases and source control repositories, detects schema changes, generates dependency-aware SyncUp scripts, and integrates with CI/CD pipelines for automated deployments.
Which databases does 4DAlert Schema Compare support?
4DAlert supports major databases including Snowflake, SQL Server, Oracle, PostgreSQL, MySQL, MongoDB, Databricks, Amazon Redshift, Google BigQuery, Azure Synapse, IBM Db2, and SAP HANA.
How do schema compare tools reduce deployment risks?
Schema compare tools automatically identify schema differences, flag potentially destructive changes such as DROP statements, generate dependency-aware deployment scripts, and provide complete audit trails to ensure safer and more reliable database deployments.